Blog
Notes on robots.txt, crawlers and technical SEO.
Start with the robots.txt guide for the basics, or use AI Fetch and the HTTP Status Checker to investigate your live pages.
November 1, 2026
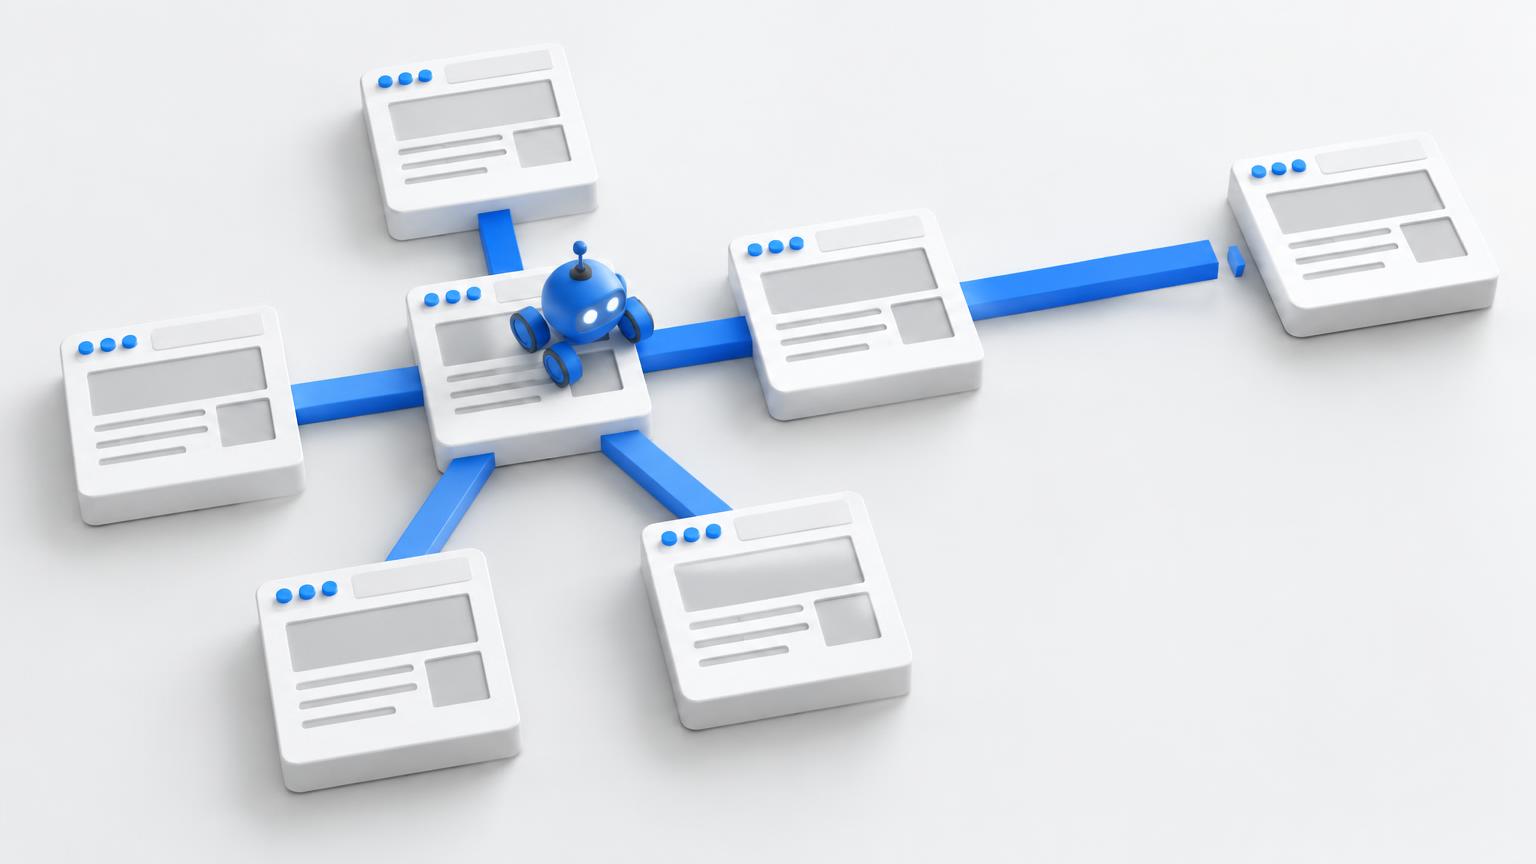
Orphan Pages: How to Find and Fix Them
Learn what orphan pages are, how to compare an internal-link crawl with other URL sources, and how to fix missing links without mistaking a limited crawl for a complete audit.
November 1, 2026
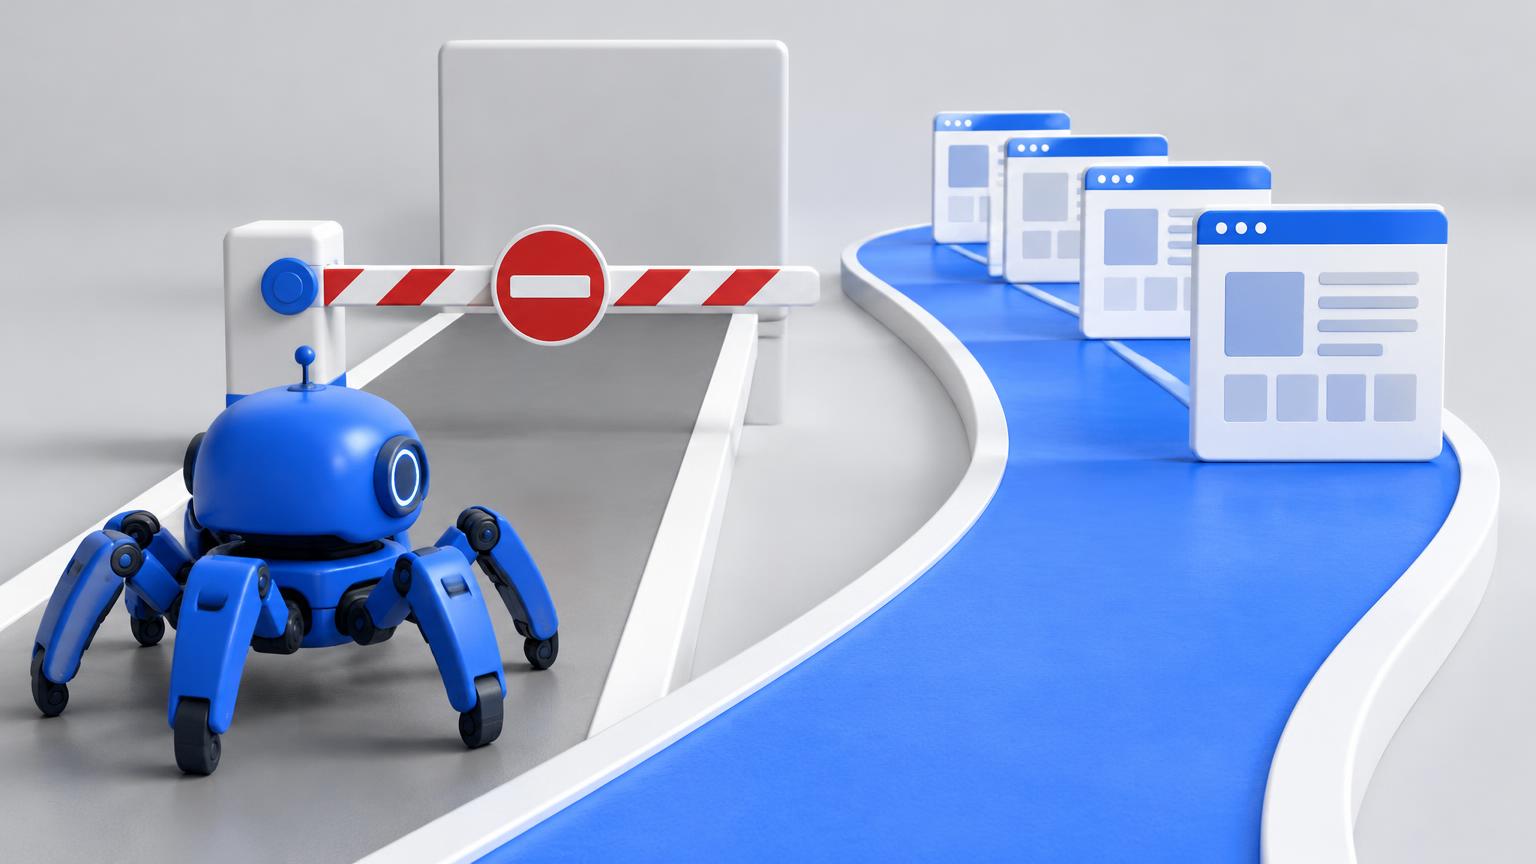
Blocked by Robots.txt: What It Means and How to Fix It
See why Google reports a URL as blocked by robots.txt, how this differs from noindex, and which fix to use when you want a page indexed, excluded or kept private.
October 19, 2026
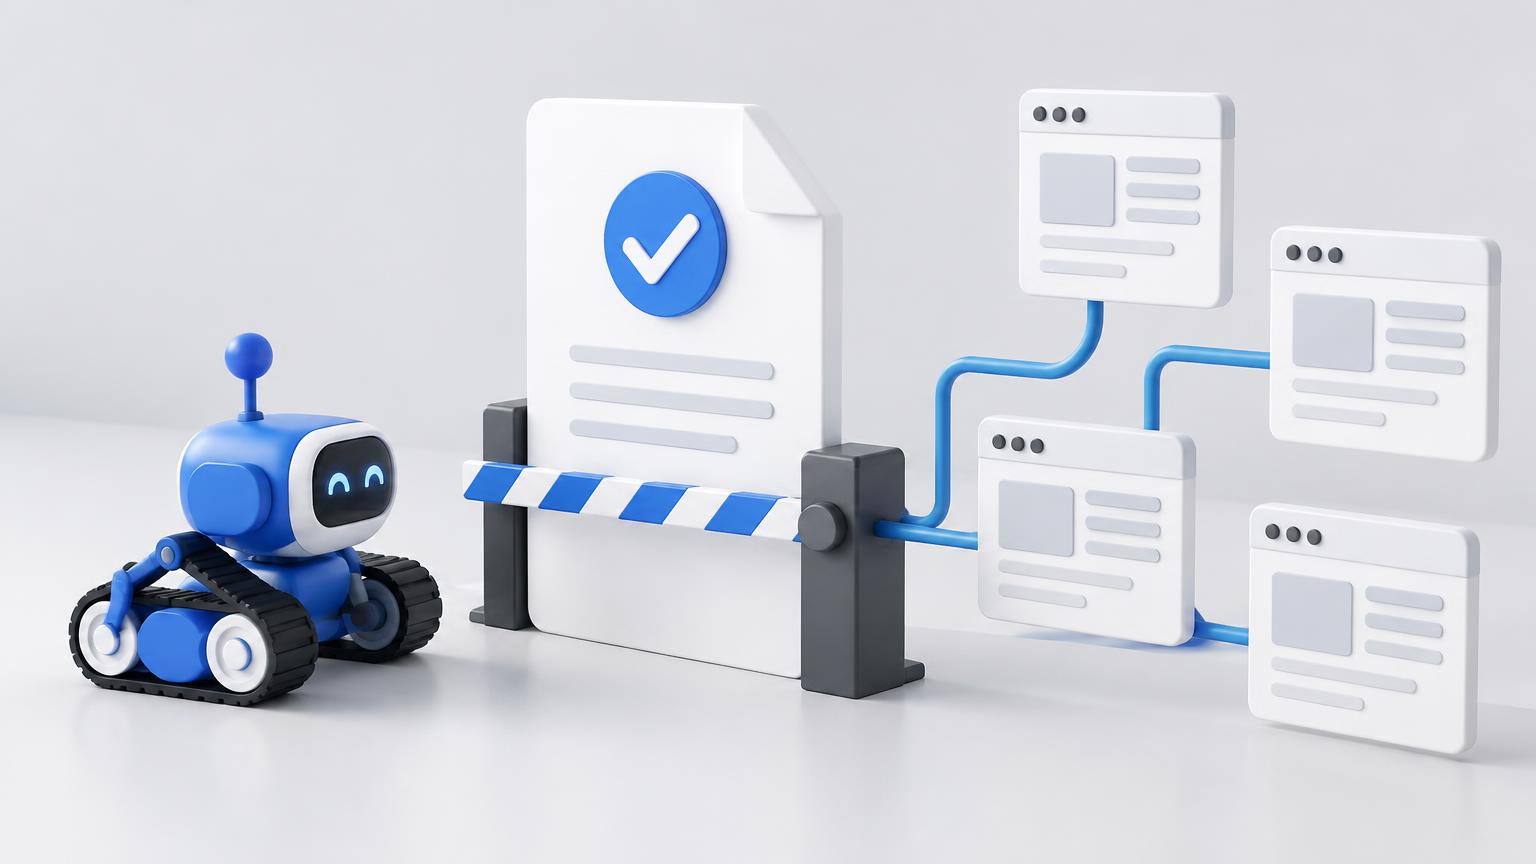
Why Robots.txt Is So Important
A tiny text file can decide how search engines crawl your whole website. Learn what robots.txt does, why it matters for crawl budget, migrations and SEO, and the mistakes to avoid.
Put what you read into practice
Check URLs against your rules and find the exact matching line.
Understand crawler groups, path matching, and rule precedence.
Create or refine a robots.txt file for the paths you want to control.