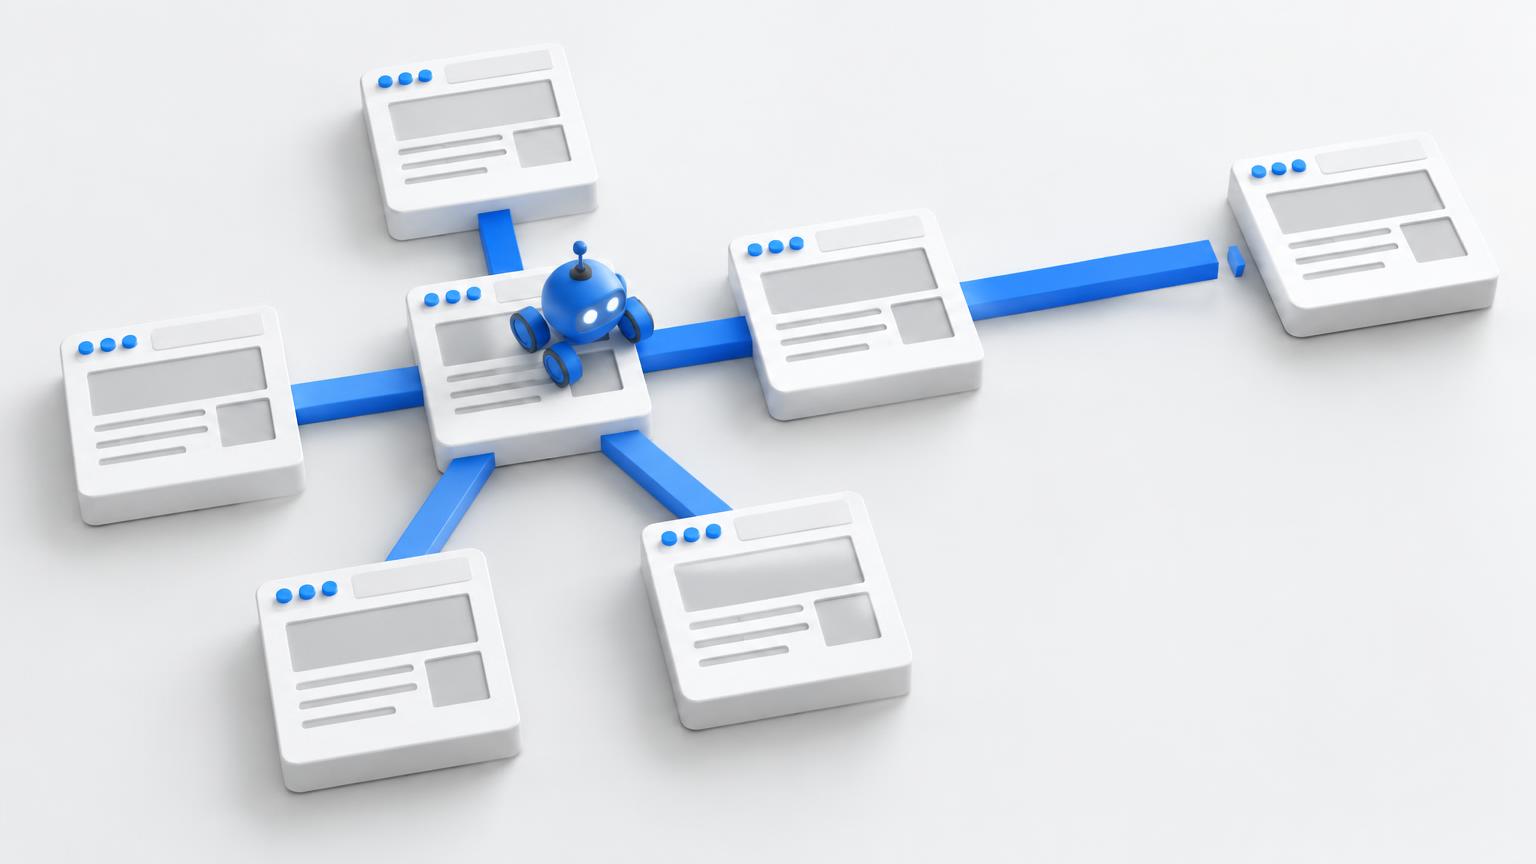
An orphan page is a page that has no incoming internal links from other pages on your website. Visitors following your site’s navigation cannot reach it, and a crawler following those links may miss it too.
But a URL that a tool did not discover is not automatically an orphan. The crawl might have stopped early, missed JavaScript links or been unable to fetch a parent page. A useful audit separates confirmed missing internal links from pages not discovered in this particular crawl.
This guide explains how to find candidates, verify the cause and decide whether to link, consolidate or retire each page.
Why orphan pages matter
Internal links give visitors a route to useful content and help search engines discover pages and understand their relationships. A valuable guide with no incoming internal links has fewer opportunities to be found while someone is browsing your site.
Google may still discover its URL through a sitemap or an external link. That does not make the site’s internal navigation complete, and discovery alone does not guarantee indexing or ranking.
Avoid treating all standalone pages as urgent SEO failures. A temporary campaign page or a private workflow page may be intentionally separate. The priority is useful public content that should be part of your site’s normal browsing experience.
Orphan, deep, blocked and unindexed are different diagnoses
| Finding | What it tells you | What to investigate |
|---|---|---|
| No incoming internal links | The page may be an orphan | Confirm against a sufficiently complete link audit |
| Several clicks from the homepage | The page is deep in the structure | Whether important content needs a clearer route |
| Present in sitemap but not in crawl | The page was not discovered by that crawl | Missing links, limits, fetch failures or rendering differences |
| Blocked by robots.txt | A crawler cannot fetch it under those rules | Whether that restriction is intentional |
| Not indexed in Google | Google has not included the page in its index | Crawlability, directives, canonical signals and content |
A page can be linked internally and still blocked. It can also be unlinked but indexed. If crawling restrictions are the problem, use the separate guide to fixing blocked by robots.txt.
Step 1: Crawl the site through internal links
Start at your homepage and follow links to other pages on the same site. Record discovered URLs and, where your audit tool supports it, which pages link to each destination.
The Internal Linking Checker offers a useful first pass: enter your site, run the check and compare the discovered pages with the sitemap pages it finds.
Understand the scope before interpreting the result. The current checker attempts up to 60 pages and follows links to a depth of three from the homepage. It looks at fetched HTML rather than running a full browser rendering process, uses same-origin paths and does not preserve query strings as separate page variants. It checks a limited set of sitemap locations and files.
Its score is a tool-specific summary of the sampled site structure, not a Google ranking score. A high score does not prove every page is linked, indexable or performing well. A low score is a starting point for investigation, not a complete diagnosis.
Step 2: Build a wider list of known URLs
A link crawl cannot reveal a page it never encounters. Compare the crawl against independent sources such as:
- XML sitemaps.
- Public page and product lists exported from your CMS.
- Search Console page data.
- Analytics landing-page reports.
- Relevant server logs or known external backlinks.
Use only data you are authorized to access. Each source has gaps: a sitemap can omit pages, analytics depends on tracking, and Search Console does not constitute a complete CMS inventory.
The useful candidate set is known URLs minus URLs discovered through internal links. The more complete both sides are, the more trustworthy that comparison becomes.
Step 3: Rule out false positives
Before calling an unmatched URL an orphan, open it and check:
- URL variants: Is it another protocol, hostname, trailing-slash version or parameterized URL of a page already found? Do not assume path case or query parameters are irrelevant on your site.
- Redirects: Does it redirect to a linked destination? Use the HTTP Status Checker to inspect the final URL and redirect chain.
- Crawl limits: Did the crawler stop before reaching the section containing the link?
- Fetch failures: Was the linking page unavailable, protected by a login or blocked by a firewall?
- JavaScript: Does the link appear only after rendering or interaction? A basic HTML crawl and a rendered crawl can discover different links.
- Actual incoming links: Does a relevant public page link to the candidate through a real, crawlable anchor?
Google can render JavaScript, but that is a separate processing stage. A link absent from the initial HTML is not proof that Google can never find it. Inspect the rendered page and use Search Console’s URL Inspection tools when necessary.
Step 4: Add useful links to pages worth keeping
For a useful page that is genuinely disconnected, choose a relevant, accessible page as the starting point. Add the link where it answers a reader’s next question.
For example, a robots.txt troubleshooting article can link to the Robots.txt Tester when discussing a blocking rule, and to the syntax reference when explaining pattern matching. The relationship is meaningful; a random list of unrelated links is not.
Use descriptive anchor text. “Check robots.txt rule syntax” is more informative than “click here.” A conventional HTML link looks like this illustrative example:
<a href="/help/shipping">Shipping information</a>
Google generally extracts crawlable links from anchor elements with an href attribute. A script-only click handler is not a reliable substitute.
Useful places to add links include related articles, category pages, product collections, navigation and breadcrumbs. Match the placement to the page’s importance and the reader’s task. There is no universal number of internal links or homepage clicks that guarantees rankings.
Step 5: Consolidate or retire pages that no longer serve a purpose
Adding links is not always the right fix.
- An old page has a genuine replacement: consider a permanent redirect to that relevant replacement, and update internal links to the final destination.
- Two pages substantially duplicate each other: review consolidation and canonical signals instead of promoting both indiscriminately.
- The content is gone with no suitable replacement: return an appropriate removal response, such as 404 or 410, and remove obsolete references.
- A page is intentionally standalone: decide whether that matches its purpose, and whether it should be indexed.
- Content is private: enforce access controls. Being unlinked does not keep a URL secret.
Do not redirect every unwanted page to the homepage simply to clear an audit report. That may give visitors an irrelevant destination without solving the original problem.
A sitemap helps discovery, but does not replace navigation
Google describes sitemaps as a way to help search engines discover URLs. A sitemap submission does not guarantee that those URLs will be crawled or indexed.
Adding a disconnected article to a sitemap may help Google learn its address, but it does not give someone reading a related article a path to it. Use both accurate sitemaps and relevant internal links.
Conversely, removing a valuable page from the sitemap does not fix its missing internal links. Fix the browsing path first when the page deserves to remain public and discoverable.
Step 6: Recheck the result
After making changes, repeat the crawl from the same starting point and confirm that the intended page is now discovered. If the audit supports incoming-link reports, check the specific source pages and anchor text as well.
Verify that the destination returns the expected response and that redirects or canonical signals do not point somewhere unintended. For Google-specific checks, inspect the page in Search Console and review later crawling and indexing reports.
Do not claim a ranking improvement just because an internal-link score rose. The first verified outcome is that the page has an accessible, relevant path from other content.
Prevent orphan pages when publishing and redesigning
Before publishing a new public page, decide where its first useful incoming link will live. Add it to the appropriate category or related content, and check the link after publication.
Repeat the audit after migrations, category changes, product removals and navigation redesigns. Pages often become disconnected when their parent category or linking article disappears.
For crawl-rule changes, the robots.txt guide explains the basics and the generator can draft a file. These tools help with crawling permissions; they do not establish whether a page has incoming internal links.
Sources
- Google: Make your links crawlable
- Google: Sitemap overview
- Google: JavaScript SEO basics
- Google: Fix search-related JavaScript problems
- Screaming Frog: How to find orphan pages
Reviewed on November 1, 2026.